
WoAI Rating
All models →Overall rating across nine build categories · Higher is better
One rating for every new model, based on real build work: web apps, games, 3D, SVG and agent tasks. Then prove it on your own prompts with your own API keys.
Model leaks, new models spotted before launch and lab news in one feed, updated every 15 minutes.
NEW · LEADERBOARDClaude Opus 5.5 leads the board at 80.0Ratings now sit on a hard scale, so the gap between frontier and open models is real.
NEW · BUILD RACERace up to four models on the same appEach one builds, gets checked in a real browser, and fixes its own bugs.
Every output is checked in a real browser and scored by a panel of judges from different labs. You pay providers directly; we never mark up inference.
Pick up to four models, describe the app in plain English, and watch them build, get checked and fix their own bugs.
Model leaks, new models spotted before launch and lab announcements land in one feed, so you can test the next model the day it drops.
You bring your own API keys, so there are no credits or usage tiers. Pro unlocks everything; Pro+ adds instant leak alerts and longer history.
Curated by World of AI from public evaluations and hands-on testing. It is hard on purpose: no model is near 100 yet, so real gaps show up.
| # | Model | Rating | Frontend | Agentic | ||||
|---|---|---|---|---|---|---|---|---|
Unlock all 86 models and every category score with Pro.Start freeUnlock with Pro | ||||||||
Pick any two of the top 20. Bars show the WoAI Rating overall and in five build categories; the winner of each row takes its lab’s color.
The rating, your own leaderboard, live runs and Build Race sit on one dashboard, in light or dark.
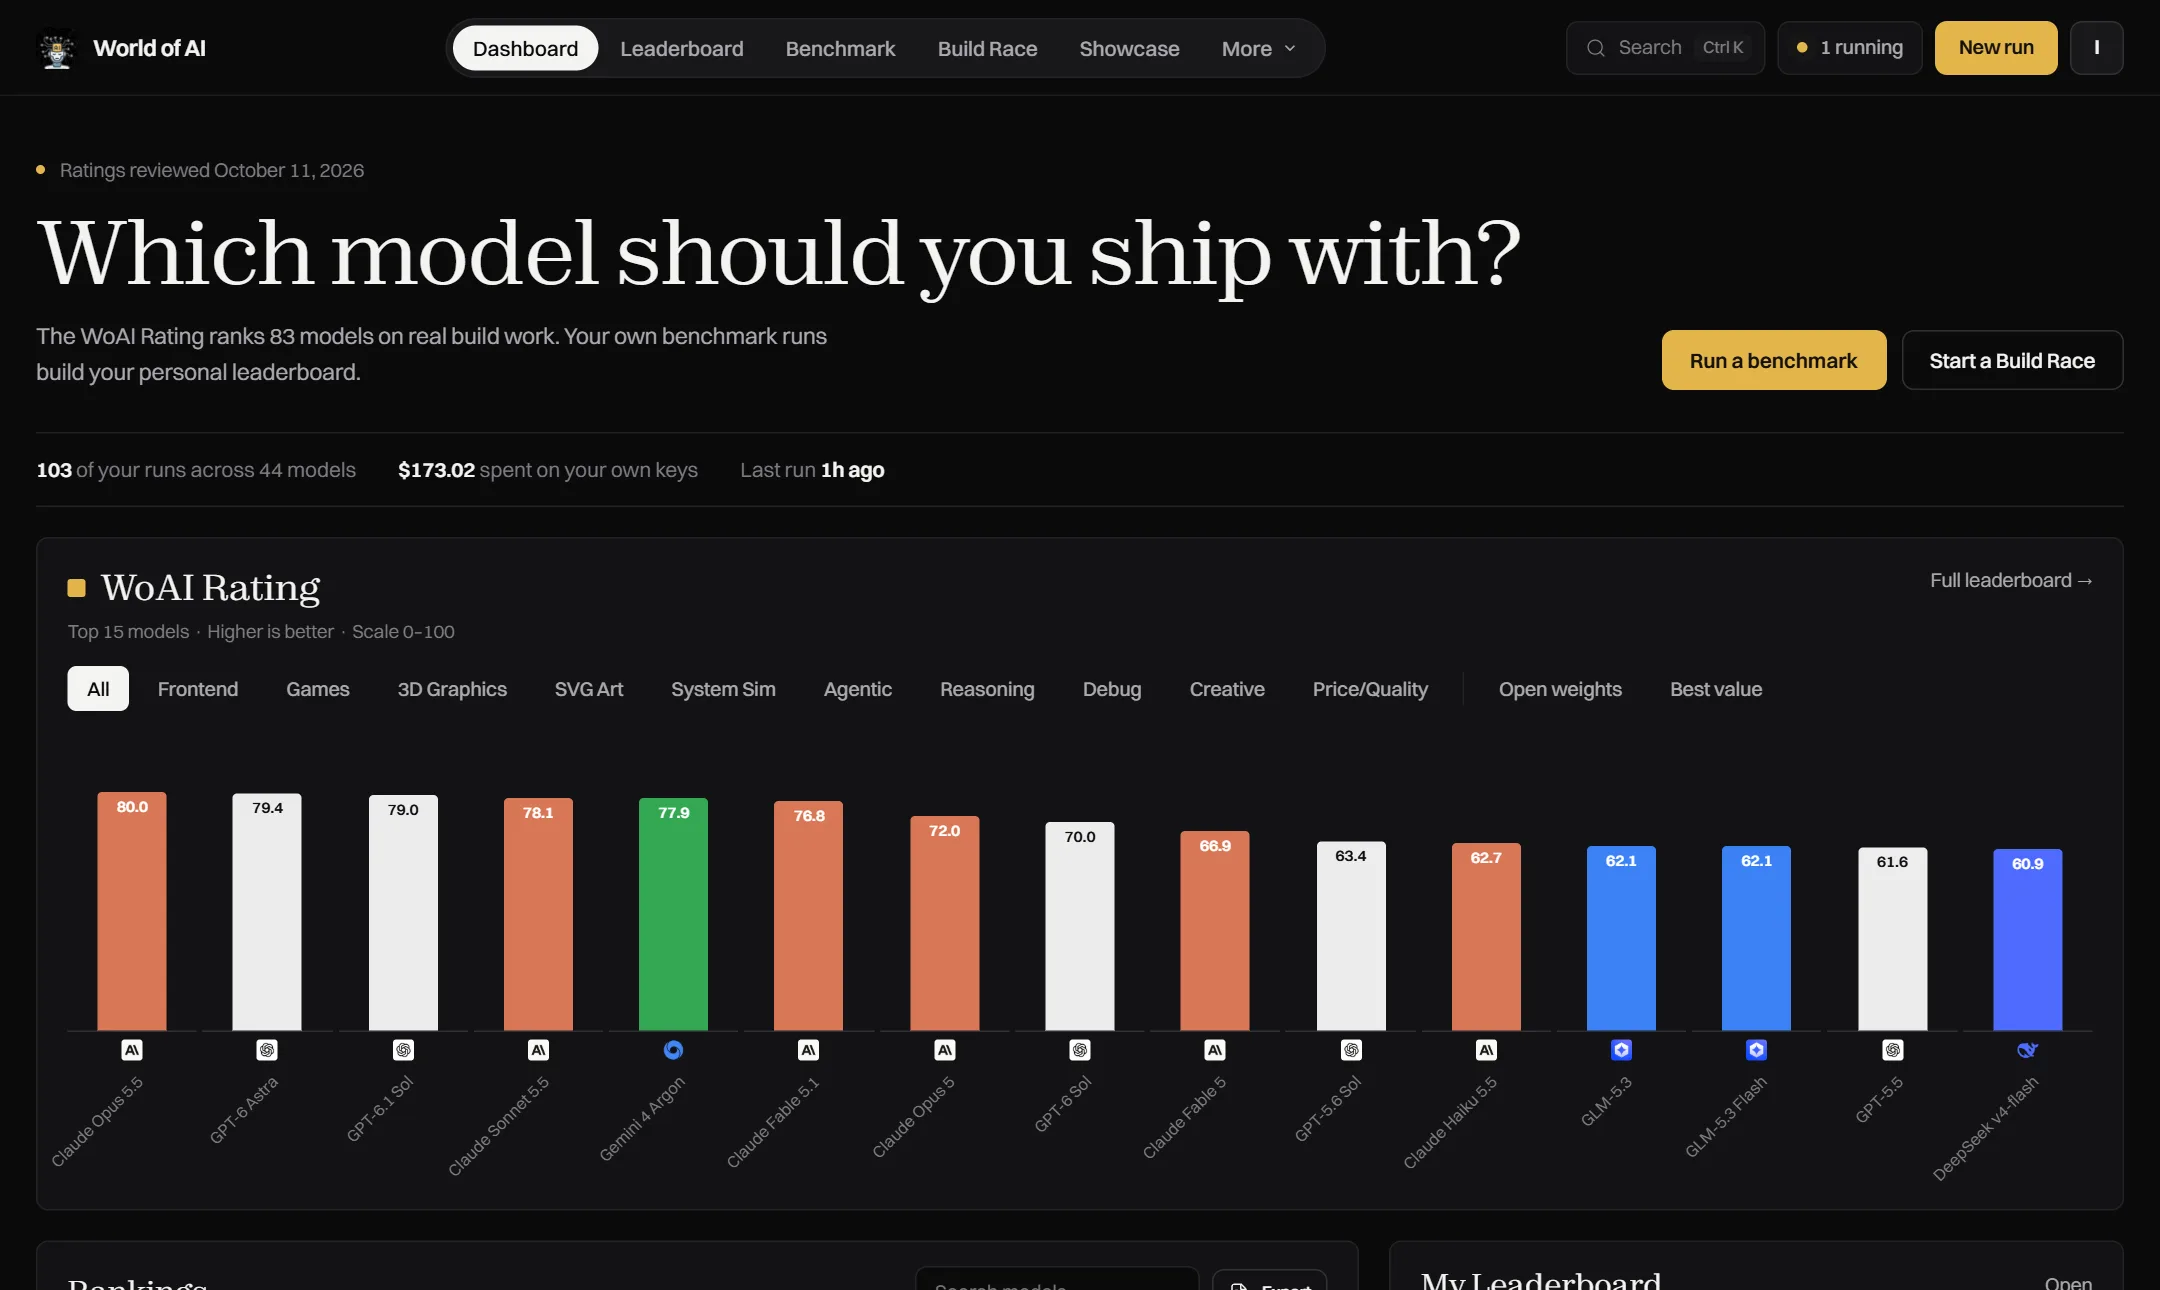
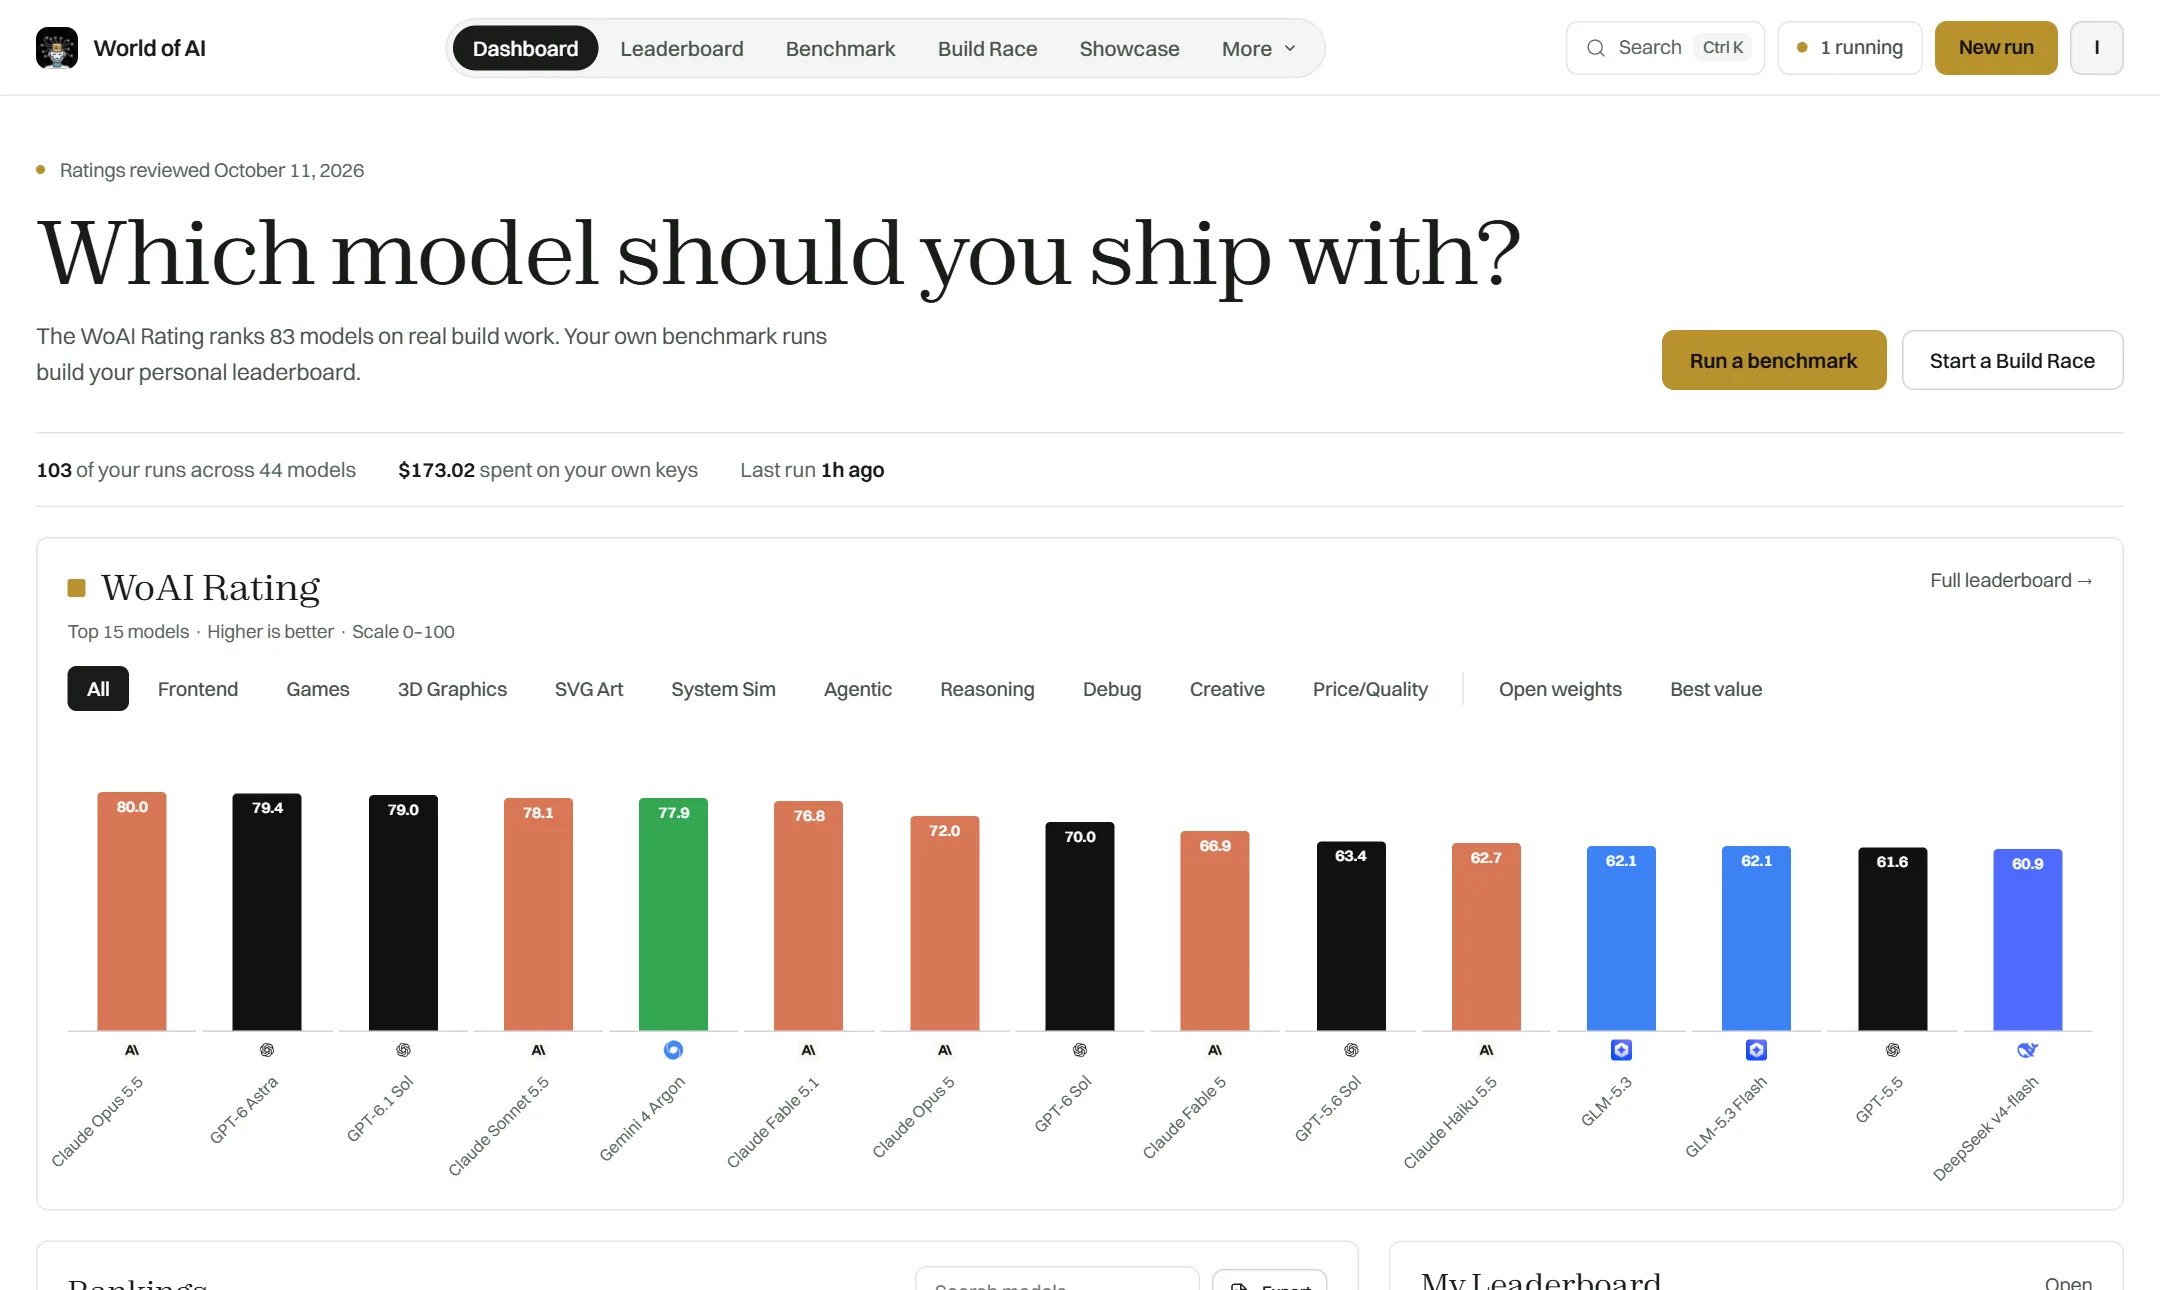
Filter the board by category, open weights or best value, and click any bar for the model page.
Every run you score lands on My Leaderboard, so your models are ranked by your work.
Watch benchmarks and Build Races progress from the top bar while you keep working.
One number you can compare at a glance, with the working shown on every model page.
120 tasks across nine categories: frontend, games, 3D, SVG, systems, agents, reasoning, debugging and creative work.
Public evaluations from across the field, checked against hands-on runs. Every model page shows how often WoAI ran it.
The nine category ratings are averaged by task count. The scale is strict, so 80 is the frontier and a weak model scores far lower.
Run any model you have a key for against your own prompts or the WoAI suite. Every score shows its working.
Yes. Create an account without a card to see the top of the leaderboard, open model pages and try one benchmark preview. Pro unlocks every model, every category score and unlimited runs on your own keys.
You use your own API keys, so providers bill you directly at their normal prices. WoAI never resells inference or adds a markup, and your keys are never shown back to the browser.
The rating is hard on purpose. A strict scale keeps real gaps visible: today’s best model rates about 80, strong models sit between 55 and 70, and weaker models fall well below that.
It is curated by World of AI from public evaluations and hands-on testing across 120 build tasks in nine categories. Each overall rating is the task-weighted average of the nine category ratings.
The full leaderboard with every model and every category score, unlimited benchmarks on your own keys with browser checks and a judge panel, My Leaderboard, run history, CSV exports, Build Race, AI News (leaks, new models and lab news, updated every 15 minutes) and the planning tools.
A Pro feed of model leaks from the accounts that find them first, new models spotted on OpenRouter and Hugging Face before launch, official lab announcements, and posts and videos from World of AI. It updates every 15 minutes, and a new model links straight to a benchmark when it is available.
Yes. Manage or cancel your plan from the billing page in your account. You keep Pro until the end of the period you paid for.
Free to start. Bring your keys when you’re ready to test.